Structured Concurrency was developed – together with Virtual Threads and Scoped Values – as part of Project Loom. It went through two incubator rounds (Java 19 and Java 20) and, since Java 21, several preview rounds. In the current version, Java 27, it is available as a seventh preview (JDK Enhancement Proposal 533).
In Java 25, the StructuredTaskScope API was fundamentally reworked by JEP 505: StructuredTaskScope and the join strategy were decoupled – the keyword here is “composition over inheritance”. The examples in this article use the current API of Java 27 throughout. Wherever something changed from Java 26 to Java 27, I point it out in an info box; the smaller changes from Java 25 to Java 26 are collected in the “History” section.
In this article, you will learn:
- Why do we need Structured Concurrency?
- What is Structured Concurrency?
- How is
StructuredTaskScopeused? - What is a policy? Which policies are there, and how can we write our own?
- What is the benefit of Structured Concurrency?
You’ll find an accompanying demo application in this GitHub repository.
Let’s first take a look at how we’ve implemented concurrent subtasks so far.
Why Do We Need Structured Concurrency?
When a task consists of several – primarily blocking – subtasks that can be performed concurrently (e.g., accessing data from a database or calling a remote API), we could previously use the Java Executor framework for this.
That might look like this (class InvoiceGenerator3_ThreadPool in the demo application):
Invoice createInvoice(int orderId, int customerId, String language)
        throws InterruptedException, ExecutionException {
    Future<Order> orderFuture =
            executor.submit(() -> orderService.getOrder(orderId));

    Future<Customer> customerFuture =
            executor.submit(() -> customerService.getCustomer(customerId));

    Future<InvoiceTemplate> invoiceTemplateFuture =
            executor.submit(() -> invoiceTemplateService.getTemplate(language));

    Order order = orderFuture.get();
    Customer customer = customerFuture.get();
    InvoiceTemplate invoiceTemplate = invoiceTemplateFuture.get();

    return Invoice.generate(order, customer, invoiceTemplate);
}
We hand the three subtasks to the executor and wait for the partial results. The happy path is implemented quickly. But how do we handle exceptions?
- If an error occurs in a subtask – how can we then cancel the other subtasks? If
orderService.getOrder(…)fails in the example above, thenorderFuture.get()throws an exception, thecreateInvoice(…)method ends, and we may have two threads still running. - How can we cancel the subtasks when the parent task (“create an invoice”) is cancelled – or when the entire application is shut down?
- How can we – in an alternative use case – cancel the remaining subtasks when only the result of a single subtask is needed?
All of this is doable, but it requires extremely complex, hard-to-maintain code (you’ll find two examples of this in the GitHub repository: InvoiceGenerator2b_CompletableFutureCancelling and InvoiceGenerator4b_NewVirtualThreadPerTaskCancelling).
And what if we want to debug code like this? A thread dump, for example, would give us loads of threads named “pool-X-thread-Y” – but we wouldn’t know which pool thread belongs to which calling thread, since all calling threads share the executor’s thread pool.
What Is Unstructured Concurrency?
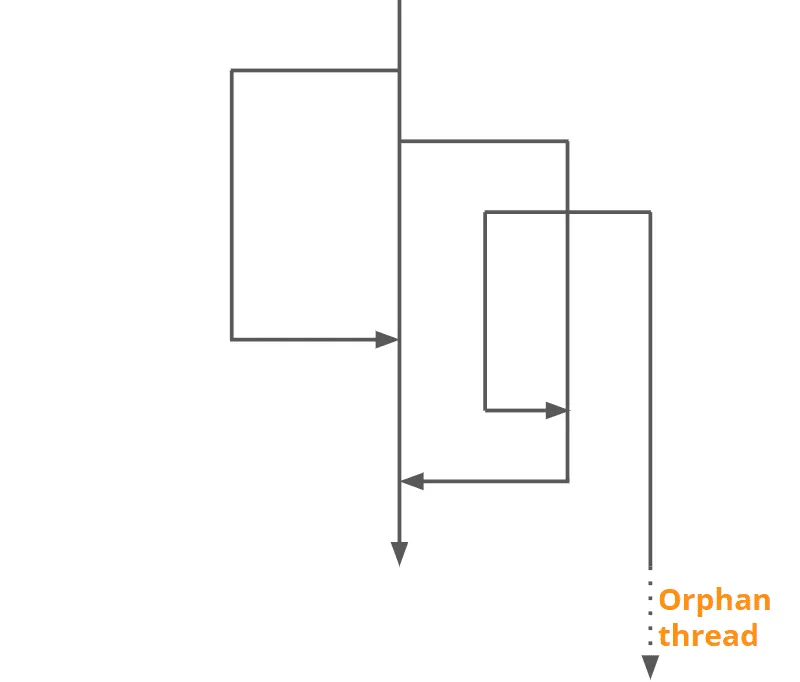
“Unstructured concurrency” means that our tasks run in a web of threads whose start and end are hard to make out in the code. Clean error handling is usually missing, and orphaned threads often result when a control structure (in the example above: the createInvoice(…) method) ends:
What Is Structured Concurrency?
Structured Concurrency is a concept that significantly improves the implementation, readability, and maintainability of code that splits a task into subtasks and processes them concurrently.
To do so, it introduces a control structure with the StructuredTaskScope interface that
- defines a clear scope, at whose start the subtasks’ threads begin and at whose end the subtasks’ threads end,
- enables clean error handling,
- and allows a clean cancellation of subtasks whose results are no longer needed.
What exactly this means, I’ll show you in the following sections with several examples.
StructuredTaskScope – A First Example
Structured Concurrency is implemented with the StructuredTaskScope interface. With it, we can rewrite the example from above as follows (class InvoiceGenerator5_StructuredTaskScope in the demo application):
Invoice createInvoice(int orderId, int customerId, String language)
    throws InterruptedException, ExecutionException {
  try (var scope = StructuredTaskScope.open()) {
    Subtask<Order> orderSubtask =
        scope.fork(() -> orderService.getOrder(orderId));

    Subtask<Customer> customerSubtask =
        scope.fork(() -> customerService.getCustomer(customerId));

    Subtask<InvoiceTemplate> invoiceTemplateSubtask =
        scope.fork(() -> invoiceTemplateService.getTemplate(language));

    scope.join();

    Order order = orderSubtask.get();
    Customer customer = customerSubtask.get();
    InvoiceTemplate template = invoiceTemplateSubtask.get();

    return Invoice.generate(order, customer, template);
  }
}
Explanation
Compared to the unstructured concurrency example, we replace the ExecutorService living in the scope of the class with a StructuredTaskScope living in the scope of the method – and executor.submit() with scope.fork(). We open the scope via the static method StructuredTaskScope.open().
With scope.fork(…) we start the subtasks; each runs in its own virtual thread by default. With scope.join() we wait for all tasks to be done. The risk of orphaned tasks no longer exists.
Afterwards, we can read the three tasks’ results via Subtask.get().
Error Handling with StructuredTaskScope
What happens if one of the three subtasks fails?
A scope opened with StructuredTaskScope.open() (without an argument) uses the default policy: as soon as a subtask throws an exception, all other subtasks are cancelled, and scope.join() throws the exception that occurred – wrapped in an ExecutionException with the original exception as its “cause”. That is the same wrapper exception you know from Future.get(). It is a checked exception, which is why createInvoice(…) declares it in its throws clause.
If you want to handle the exception after the scope has been closed, you add a catch block:
try (var scope = StructuredTaskScope.open()) {
  // fork(…) and join() ...
} catch (ExecutionException e) {
  Throwable cause = e.getCause();
  switch (cause) {
    case OrderNotFoundException onfe -> // ...
    default -> // ...
  }
}Running the Example Code
If you’d like to try the example yourself: StructuredTaskScope is still a preview feature in Java 27 and must be enabled explicitly. When compiling, use javac --release 27 --enable-preview; when running, use java --enable-preview. Preview features can only be compiled with the exact Java version they belong to – so you need a JDK 27 for the examples. You’ll find detailed instructions in the demo application’s README; for Java 21, 25, and 26, the repository has tags with the matching code.
In the example code, the three subtasks throw an exception with a certain probability. If you start the program a few times, you’ll see how an exception in one task leads to an interruption in the other tasks and to the program terminating:
$ java -cp target/classes --enable-preview \
    eu.happycoders.structuredconcurrency.demo1_invoice.InvoiceGenerator5_StructuredTaskScope

[Thread[#3,main,5,main]] Forking tasks
[VirtualThread[#34]/runnable@ForkJoinPool-1-worker-1] Loading order
[VirtualThread[#36]/runnable@ForkJoinPool-1-worker-2] Loading customer
[Thread[#3,main,5,main]] Waiting for all tasks to finish
[VirtualThread[#39]/runnable@ForkJoinPool-1-worker-3] Loading template
[VirtualThread[#39]/runnable@ForkJoinPool-1-worker-1] Error loading template
[VirtualThread[#34]/runnable@ForkJoinPool-1-worker-2] Order loading was interrupted
[VirtualThread[#36]/runnable@ForkJoinPool-1-worker-2] Customer loading was interrupted
Exception in thread "main" java.util.concurrent.ExecutionException: java.lang.RuntimeException: Error loading template
        [...]
You can also tell from this output that all tasks run in virtual threads.
Policies via Joiners
A so-called policy defines what happens when a subtask finishes or throws an exception. In addition, a policy can define a return value for scope.join().
In the example above, we used the default policy: wait for all subtasks, cancel on the first failure. You select other policies by passing a Joiner to the open() method. A Joiner handles the completion of the subtasks and produces the result for scope.join(). Depending on the joiner, join() returns a single result, a list, or null.
“Any Successful Result”
Sometimes we don’t need all results, just the first successful one. Example: we want to verify a customer address via several external APIs simultaneously and use only the first result.
For this, there’s the joiner anySuccessfulOrThrow(). As soon as one subtask has succeeded, the scope is cancelled and the remaining subtasks are interrupted. scope.join() then returns the result of the successful subtask (class AddressVerification2_AnySuccessful in the demo application):
AddressVerificationResponse verifyAddress(Address address)
    throws InterruptedException, ExecutionException {
  try (var scope = StructuredTaskScope.open(
      Joiner.<AddressVerificationResponse>anySuccessfulOrThrow())) {
    log("Forking tasks");

    scope.fork(() -> verificationService.verifyViaServiceA(address));
    scope.fork(() -> verificationService.verifyViaServiceB(address));
    scope.fork(() -> verificationService.verifyViaServiceC(address));

    log("Waiting for one task to finish");

    return scope.join();
  }
}
Should, against expectations, all three calls throw an exception, scope.join() throws one of them, wrapped in an ExecutionException.
When you run the example code, you’ll see how the first successful subtask leads to a result and the other tasks are cancelled:
$ java -cp target/classes --enable-preview \
    eu.happycoders.structuredconcurrency.demo2_address.AddressVerification2_AnySuccessful

[Thread[#3,main,5,main]] Forking tasks
[Thread[#3,main,5,main]] Waiting for one task to finish
[VirtualThread[#34]/runnable@ForkJoinPool-1-worker-1] Verifying address via service A
[VirtualThread[#38]/runnable@ForkJoinPool-1-worker-2] Verifying address via service C
[VirtualThread[#36]/runnable@ForkJoinPool-1-worker-4] Verifying address via service B
[VirtualThread[#34]/runnable@ForkJoinPool-1-worker-2] Error loading address via service A
[VirtualThread[#38]/runnable@ForkJoinPool-1-worker-2] Finished loading address via service C
[VirtualThread[#36]/runnable@ForkJoinPool-1-worker-5] Verifying address via service B was interrupted
[Thread[#3,main,5,main]] Response: AddressVerificationResponse[value=Verification response from service C]
All Joiners at a Glance
In Java 27, the following predefined joiners are available to you:
| Joiner | Description |
|---|---|
no joiner or Joiner.awaitAllSuccessfulOrThrow() | An exception in a subtask immediately cancels the scope; scope.join() throws the exception wrapped in an ExecutionException. If all subtasks succeed, scope.join() ends without an exception and returns null. The results must be read from the Subtask objects returned by scope.fork(). |
Joiner.anySuccessfulOrThrow() | scope.join() returns the result of the first successful subtask; the other subtasks are cancelled. If all fail, scope.join() throws the exception of one of the failed subtasks wrapped in an ExecutionException. |
Joiner.allSuccessfulOrThrow() | Like no joiner or awaitAllSuccessfulOrThrow() – with the difference that scope.join() returns a List of the results on success. An exception cancels the scope and results in an ExecutionException. |
Joiner.allUntil( | scope.join() waits until either all subtasks have finished – whether successfully or not – or the given predicate matches a finished subtask. Returns a List of the Subtask objects. |
Since Java 27, the three …OrThrow joiners also come in a variant that takes a function producing the wrapper exception. If you want join() to throw, for example, a CompletionException (which doesn’t have to be declared) instead of an ExecutionException, you write:
try (var scope = StructuredTaskScope.open(
    Joiner.<SupplierDeliveryTime, CompletionException>allSuccessfulOrThrow(
        CompletionException::new))) {
  // fork(…) ...

  return scope.join(); // throws CompletionException instead of ExecutionException
}Your Own Policy: A Custom Joiner
If none of the predefined joiners suits your use case, you can write your own with relatively little effort.
Let’s assume we want to check the availability of a product at several suppliers – and not use the first result, but the one with the fastest availability. At the same time, we only want to propagate failed requests if the requests failed at all suppliers.
This can be implemented surprisingly easily – and at the same time reusably for other scenarios – by implementing the Joiner interface (class BestResultJoiner in the demo application). Its three type parameters, Joiner<T, R, R_X>, stand for the result type of the subtasks, the return type of join(), and the exception type that join() may throw:
public class BestResultJoiner<T>
    implements Joiner<T, T, SupplierDeliveryTimeCheckException> {

  private final Comparator<T> comparator;

  private T bestResult;
  private final List<Throwable> exceptions =
      Collections.synchronizedList(new ArrayList<>());

  public BestResultJoiner(Comparator<T> comparator) {
    this.comparator = comparator;
  }

  @Override
  public boolean onComplete(Subtask<T> subtask) {
    switch (subtask.state()) {
      case UNAVAILABLE -> {
        // Ignore
      }
      case SUCCESS -> {
        T result = subtask.get();
        synchronized (this) {
          if (bestResult == null
              || comparator.compare(result, bestResult) > 0) {
            bestResult = result;
          }
        }
      }
      case FAILED -> exceptions.add(subtask.exception());
    }

    return false; // Don't cancel the scope
  }

  @Override
  public T result() throws SupplierDeliveryTimeCheckException {
    if (bestResult != null) {
      return bestResult;
    } else {
      SupplierDeliveryTimeCheckException exception =
          new SupplierDeliveryTimeCheckException();
      exceptions.forEach(exception::addSuppressed);
      throw exception;
    }
  }

  @Override
  public T timeout() throws SupplierDeliveryTimeCheckException {
    if (bestResult != null) {
      return bestResult; // The best result received before the timeout
    } else {
      SupplierDeliveryTimeCheckException exception =
          new SupplierDeliveryTimeCheckException(new CancelledByTimeoutException());
      exceptions.forEach(exception::addSuppressed);
      throw exception;
    }
  }
}
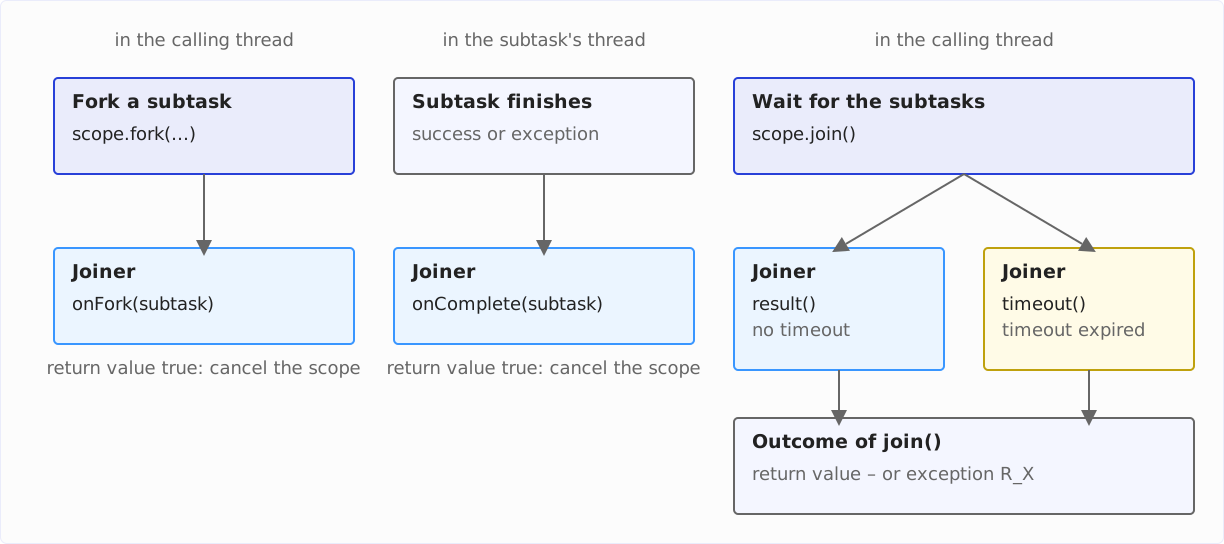
The onComplete() method is called for every finished subtask – both for successful ones and for those that threw an exception. We check which case occurred with subtask.state(). In the success case, we fetch the result with subtask.get() and write it – if it’s better than the best so far – into the bestResult field in a thread-safe manner. In the case of an exception, we collect it in a list in a thread-safe manner. Both have to be thread-safe because onComplete() doesn’t run in the calling thread, but in the thread of the respective subtask.
The return value of onComplete() indicates whether the scope should be cancelled (true means cancel). Since we want to wait for all suppliers, we always return false here.
The result() method is called by scope.join() once all subtasks have finished or the scope has been cancelled. It checks whether a successful result exists and returns it. Otherwise, it throws a SupplierDeliveryTimeCheckException, to which it attaches the collected exceptions as “suppressed exceptions”.
The timeout() method is called instead if a timeout is configured for the scope and it expires before all subtasks have finished (more on this shortly). Our joiner then returns the best result received up to that point. If there is none yet, it throws a SupplierDeliveryTimeCheckException with a CancelledByTimeoutException as the “cause” – that is what the contract of the Joiner interface requires.
A fourth method, onFork(), is called by scope.fork(…) before each subtask starts; it, too, can cancel the scope by returning true. Our joiner leaves it at the default implementation, which returns false.
The following diagram shows which method of the joiner is called when, and in which thread:
We use the joiner as follows (class SupplierDeliveryTimeCheck2_StructuredTaskScope in the demo application):
SupplierDeliveryTime getSupplierDeliveryTime(
    String productId, List<String> supplierIds)
    throws InterruptedException, SupplierDeliveryTimeCheckException {
  try (var scope = StructuredTaskScope.open(
      new BestResultJoiner<SupplierDeliveryTime>(
          Comparator.comparing(
              SupplierDeliveryTime::deliveryTimeHours).reversed()))) {
    for (String supplierId : supplierIds) {
      scope.fork(() -> service.getDeliveryTime(productId, supplierId));
    }

    return scope.join();
  }
}
scope.join() returns the result of our joiner’s result() method here. If all supplier requests fail, result() throws a SupplierDeliveryTimeCheckException – and scope.join() rethrows it unchanged. Through the joiner’s third type parameter, this exception type is part of the signature of join(); calling code thus gets a precise exception contract that the compiler checks.
The output of the example program might look like this:
$ java -cp target/classes --enable-preview \
    eu.happycoders.structuredconcurrency.demo3_suppliers.SupplierDeliveryTimeCheck2_StructuredTaskScope

[VirtualThread[#34]/runnable@ForkJoinPool-1-worker-1] Retrieving delivery time from supplier A
[VirtualThread[#36]/runnable@ForkJoinPool-1-worker-3] Retrieving delivery time from supplier B
[VirtualThread[#38]/runnable@ForkJoinPool-1-worker-4] Retrieving delivery time from supplier D
[VirtualThread[#39]/runnable@ForkJoinPool-1-worker-5] Retrieving delivery time from supplier E
[VirtualThread[#37]/runnable@ForkJoinPool-1-worker-1] Retrieving delivery time from supplier C
[VirtualThread[#34]/runnable@ForkJoinPool-1-worker-1] Finished retrieving delivery time from supplier A: 12 hours
[VirtualThread[#37]/runnable@ForkJoinPool-1-worker-1] Finished retrieving delivery time from supplier C: 144 hours
[VirtualThread[#39]/runnable@ForkJoinPool-1-worker-1] Finished retrieving delivery time from supplier E: 64 hours
[VirtualThread[#38]/runnable@ForkJoinPool-1-worker-1] Error retrieving delivery time from supplier D
[VirtualThread[#36]/runnable@ForkJoinPool-1-worker-1] Error retrieving delivery time from supplier B
[Thread[#3,main,5,main]] Response: SupplierDeliveryTime[supplier=A, deliveryTimeHours=12]
Nice to see: although the calls for suppliers B and D failed, the remaining suppliers did deliver results – and in the end, the best result is returned: supplier A with a delivery time of 12 hours.
Nested StructuredTaskScopes
If we don’t just want to query the suppliers for one product simultaneously, but the suppliers for several products, we can solve this quite easily with nested scopes (class SupplierDeliveryTimeCheck3_NestedStructuredTaskScope in the demo application). This time, we use Joiner.allSuccessfulOrThrow() to get a list of the results directly from scope.join():
List<SupplierDeliveryTime> getSupplierDeliveryTimes(
    List<String> productIds, List<String> supplierIds)
    throws InterruptedException, ExecutionException {
  try (var scope = StructuredTaskScope.open(
      Joiner.<SupplierDeliveryTime>allSuccessfulOrThrow())) {
    productIds.forEach(productId ->
        scope.fork(() -> getSupplierDeliveryTime(productId, supplierIds)));

    return scope.join();
  }
}
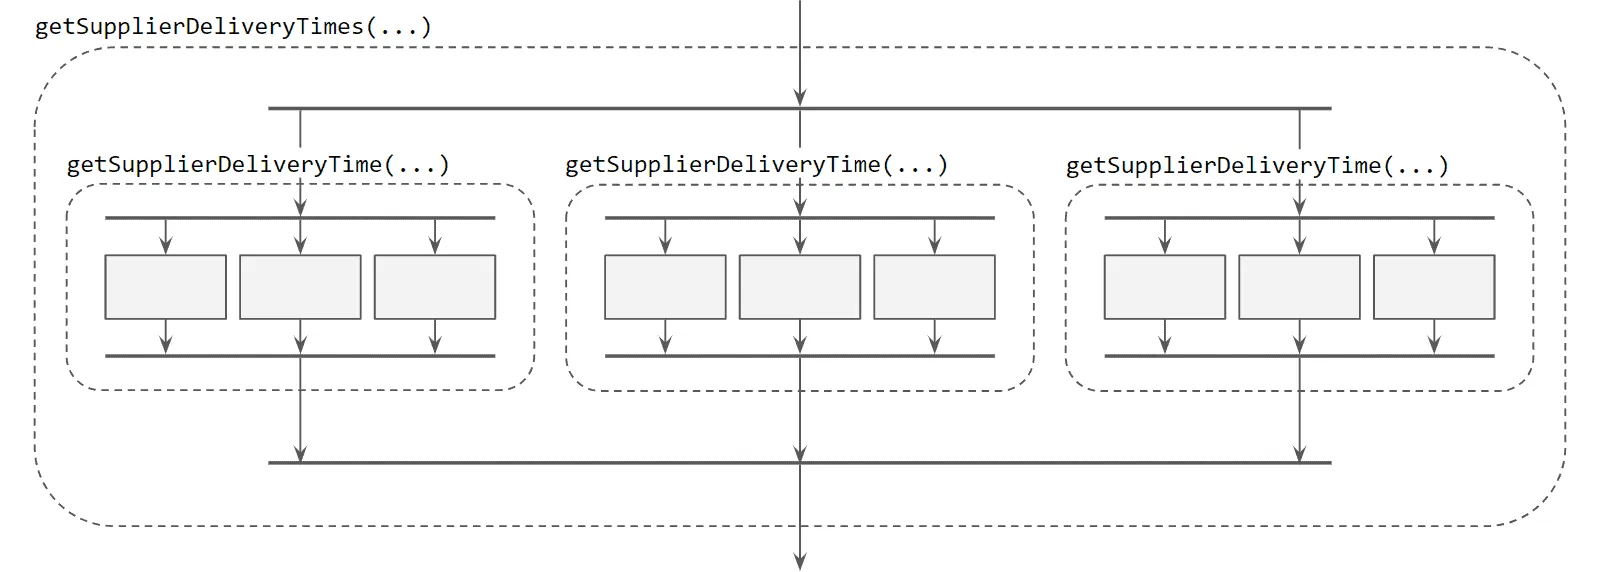
We create a StructuredTaskScope – and within this scope we fork subtasks that in turn call the method getSupplierDeliveryTime(…) shown in the previous section. That method opens a scope of its own, which is thus nested within the scope of getSupplierDeliveryTimes(…).
The following diagram shows these scopes as dashed lines:
Setting a Timeout for a Scope
What if we don’t want to wait for the subtasks indefinitely? Via the configuring variant of the open() method, you can give the scope a timeout – here for the nested example from the previous section (class SupplierDeliveryTimeCheck5_Timeout in the demo application):
List<SupplierDeliveryTime> getSupplierDeliveryTimes(
    List<String> productIds, List<String> supplierIds, Duration timeout)
    throws InterruptedException, ExecutionException {
  try (var scope = StructuredTaskScope.open(
      Joiner.<SupplierDeliveryTime>allSuccessfulOrThrow(),
      cf -> cf.withTimeout(timeout))) {
    productIds.forEach(productId ->
        scope.fork(() -> getSupplierDeliveryTime(productId, supplierIds)));

    return scope.join();
  }
}
If the timeout expires before all subtasks are finished, the scope is cancelled, all subtasks still running are interrupted, and scope.join() calls the joiner’s timeout() method. The three …OrThrow joiners then throw an ExecutionException with a CancelledByTimeoutException as the “cause”; allUntil() returns the list of Subtask objects, however far they got; and our BestResultJoiner returns the best result received up to that point.
Whether a subtask failed or the timeout expired is best distinguished with a pattern-matching switch over the “cause” – this is how the demo class’s main() method does it:
} catch (ExecutionException e) {
  switch (e.getCause()) {
    case CancelledByTimeoutException _ ->
        log("Timeout while retrieving delivery times");
    case Throwable cause -> log("Error retrieving delivery times: " + cause);
  }
}
With a timeout of 500 ms – the simulated suppliers take between 250 ms and one second – a run of the example program looks like this, for example:
$ java -cp target/classes --enable-preview \
    eu.happycoders.structuredconcurrency.demo3_suppliers.SupplierDeliveryTimeCheck5_Timeout

[VirtualThread[#47]/runnable@ForkJoinPool-1-worker-5] Retrieving delivery time from supplier B
[VirtualThread[#48]/runnable@ForkJoinPool-1-worker-12] Retrieving delivery time from supplier C
[VirtualThread[#50]/runnable@ForkJoinPool-1-worker-1] Retrieving delivery time from supplier E
        [...]
[VirtualThread[#52]/runnable@ForkJoinPool-1-worker-10] Error retrieving delivery time from supplier C
[VirtualThread[#42]/runnable@ForkJoinPool-1-worker-10] Finished retrieving delivery time from supplier A: 15 hours
[VirtualThread[#60]/runnable@ForkJoinPool-1-worker-10] Finished retrieving delivery time from supplier C: 110 hours
[VirtualThread[#53]/runnable@ForkJoinPool-1-worker-10] Finished retrieving delivery time from supplier D: 104 hours
[VirtualThread[#65]/runnable@ForkJoinPool-1-worker-5] Retrieving delivery time from supplier D interrupted
[VirtualThread[#49]/runnable@ForkJoinPool-1-worker-3] Retrieving delivery time from supplier D interrupted
        [...]
[Thread[#3,main,5,main]] Timeout while retrieving delivery timesBenefits of Structured Concurrency
Structured Concurrency is characterized by clearly visible start and end points of concurrent subtasks in the code. Errors in the subtasks are propagated to the parent scope. This makes the code easier to read and maintain and ensures that, by the end of a scope, all started threads have terminated.
The following diagram contrasts unstructured and structured concurrency:
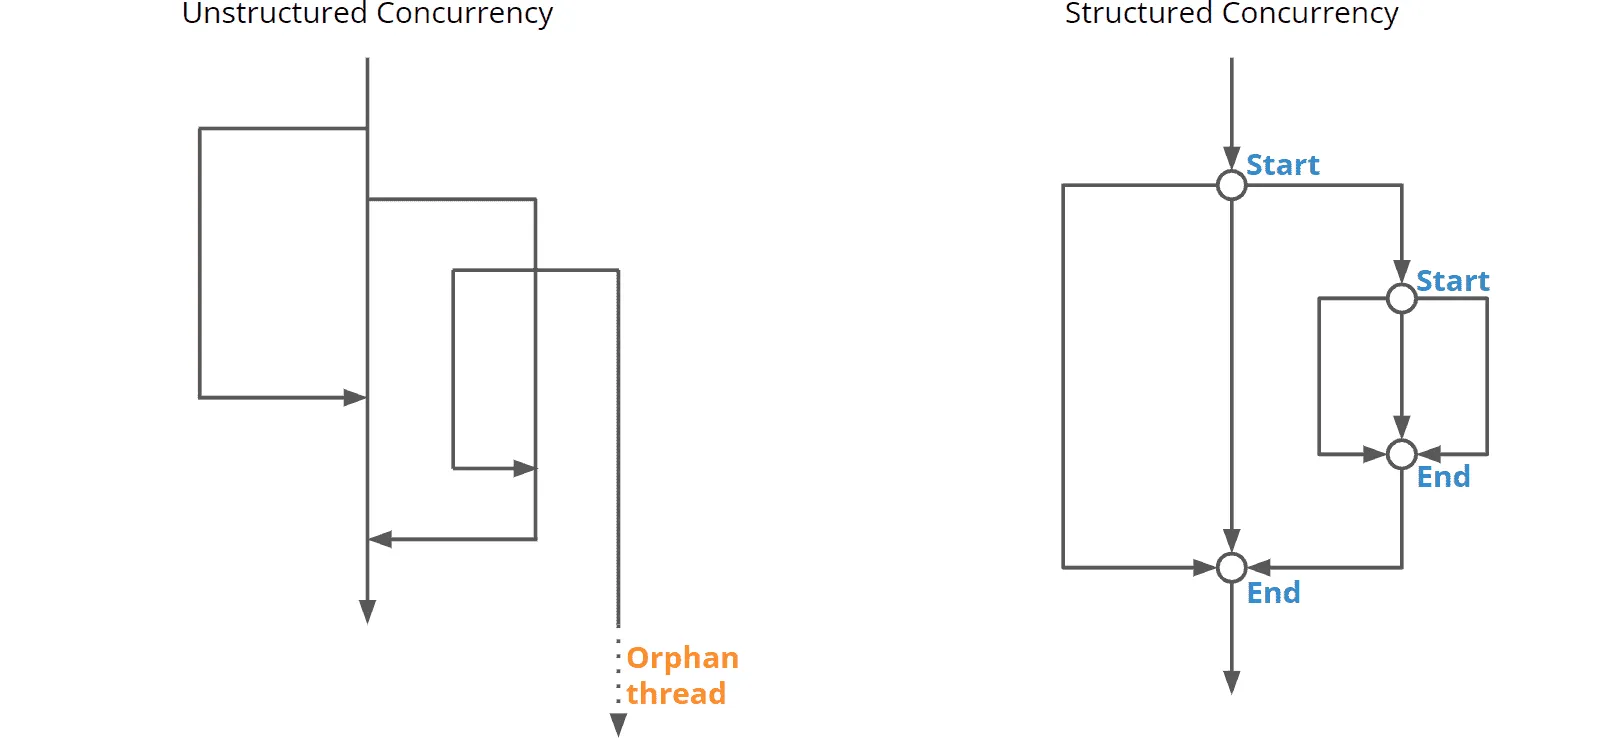
Benefits of StructuredTaskScope
With StructuredTaskScope, we have a language construct for Structured Concurrency:
- Task and subtasks form a self-contained unit in the code – there is no
ExecutorServicein a higher scope, such as that of the class. The threads don’t come from a thread pool; instead, each subtask is executed in a new virtual thread. - The scope spanned by the try-with-resources block gives us clear start and end points for all threads.
- At the end of the scope, all threads have terminated.
- Errors within the subtasks are cleanly propagated to the parent scope.
- Depending on the policy, the remaining subtasks are cancelled when a subtask has succeeded or when an error occurred in a subtask.
- When the calling thread is cancelled, the subtasks are cancelled as well.
In addition, StructuredTaskScope helps with debugging: when we output a thread dump in JSON format (jcmd <pid> Thread.dump_to_file -format=json <file>), it shows the call hierarchy between parent and child threads.
StructuredTaskScope and Scoped Values
The Scoped Values finalized in Java 25 are automatically inherited by all child threads created via StructuredTaskScope.fork(…) when StructuredTaskScope is used within a scope.
How exactly this works, I’ll show you with the following code example (class SupplierDeliveryTimeCheck4_NestedStructuredTaskScopeUsingScopedValue in the demo application).
We create a ScopedValue – in the example for an API key –, bind it to the API key, and then call the method getSupplierDeliveryTimes(…) shown in the “Nested StructuredTaskScopes” section within the scope via call():
public static final ScopedValue<String> API_KEY = ScopedValue.newInstance();

List<SupplierDeliveryTime> getSupplierDeliveryTimes(List<String> productIds,
        List<String> supplierIds, String apiKey) throws Exception {
    return ScopedValue.where(API_KEY, apiKey)
            .call(() -> getSupplierDeliveryTimes(productIds, supplierIds));
}
Thanks to the inheritance of the scoped value API_KEY, it can also be accessed within the SupplierDeliveryTimeService.getDeliveryTime(…) method without having to thread it through via method arguments – and that even when the methods aren’t executed in the thread that calls ScopedValue.where(…), but in the child threads – or, in this example, even grandchild threads – created via StructuredTaskScope.fork(…).
History
Structured Concurrency was defined in the following JDK Enhancement Proposals:
- Java 19: JEP 428: Structured Concurrency (Incubator)
- Java 20: JEP 437: Structured Concurrency (Second Incubator)
- Java 21: JEP 453: Structured Concurrency (Preview)
- Java 22: JEP 462: Structured Concurrency (Second Preview)
- Java 23: JEP 480: Structured Concurrency (Third Preview)
- Java 24: JEP 499: Structured Concurrency (Fourth Preview)
- Java 25: JEP 505: Structured Concurrency (Fifth Preview)
- Java 26: JEP 525: Structured Concurrency (Sixth Preview)
- Java 27: JEP 533: Structured Concurrency (Seventh Preview)
The changes from Java 26 to Java 27 are in the info boxes above. The smaller changes from Java 25 to Java 26 (JEP 525) at a glance:
Joiner.anySuccessfulResultOrThrow()was renamed toanySuccessfulOrThrow()– the word “Result” doesn’t appear in the other joiner names either.- With
allSuccessfulOrThrow(),join()returns aListof the results directly instead of aStreamof theSubtaskobjects;scope.join().map(Subtask::get).toList()becamescope.join(). - The configuring
open()method takes aUnaryOperator<Configuration>instead of aFunction. - The
Joinerinterface gained theonTimeout()method – which Java 27 has already replaced bytimeout().
Conclusion
Structured Concurrency – building on virtual threads – significantly simplifies managing tasks that are split into concurrent subtasks. Policies let us influence the behavior of StructuredTaskScope, e.g., to cancel all tasks should one of them fail.
The API was fundamentally reworked in Java 25: StructuredTaskScope and the join strategy were decoupled, which leads to more clearly structured, more understandable, and more robust code – the keyword here is “composition over inheritance”. In Java 26 (JEP 525), minor adjustments followed, which I’ve summarized in the history.
Please note that Structured Concurrency is still in the preview stage – in Java 27 as the seventh preview (JEP 533). The API may therefore still change. Above all, Java 27 sharpened the exception handling: the predefined joiners throw an ExecutionException instead of a FailedException, a third type parameter makes the exception type thrown by join() explicit, timeout() replaces onTimeout(), awaitAll() is gone, and open() accepts the configuration without a joiner, too. You’ll find the details in the “Java 26 → Java 27” info boxes above.
Did this article save you time? Then I’d be happy if you invested a minute of it in a review on my ProvenExpert profile. Your feedback shows me that the work on these articles pays off.